Wiring Usage Analytics Into an AI Agent via MCP Without Touching a UI
Agents get consistent usage answers only from a governed metrics layer.
Wiring usage analytics into an AI agent via MCP requires a governed data layer. For API-first and agent-first teams, the right headless analytics backend exposes defined metrics through an API, enforces identity-scoped access, and returns context with every value.
What MCP actually does when an AI agent asks for usage data
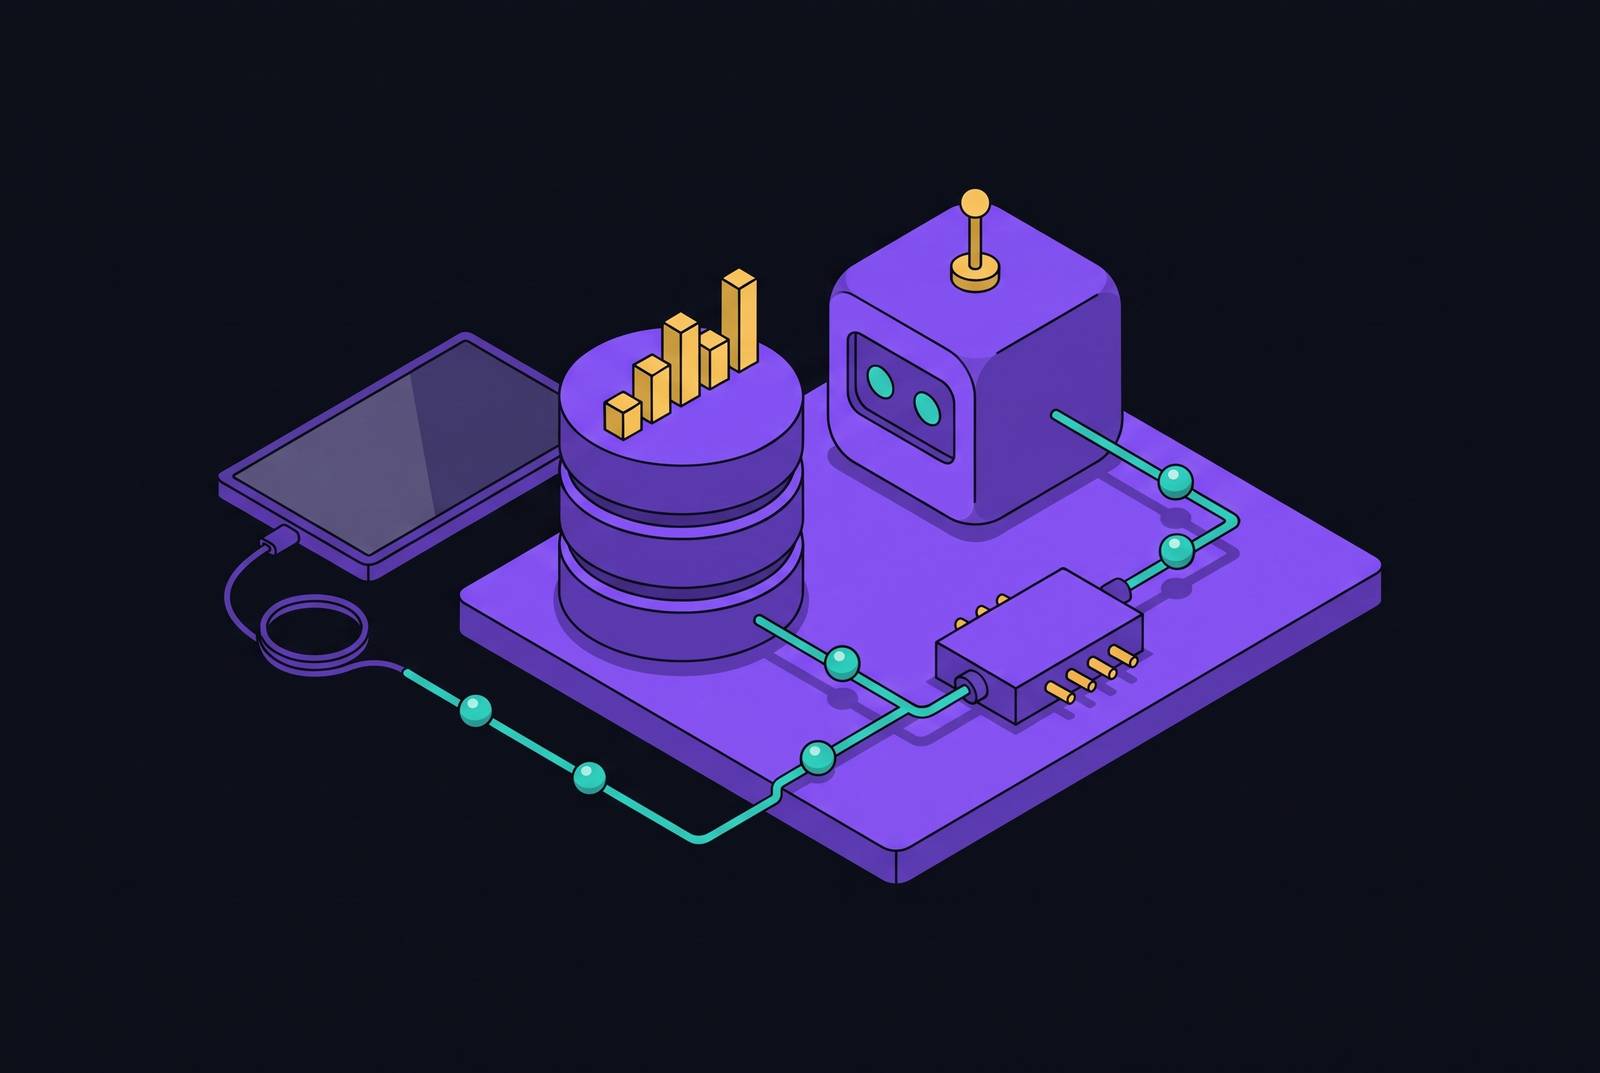
An agent that asks how activation rate changed can use MCP to reach an analytics resource without opening a dashboard. The AI client makes the request, the MCP server handles the connection, and the resource supplies the data. That resource may be a database or an API. The server handles authentication tokens, rate limits, schema mapping, and errors so the agent does not need to know how the database is structured. The agent can then present the result in natural language.
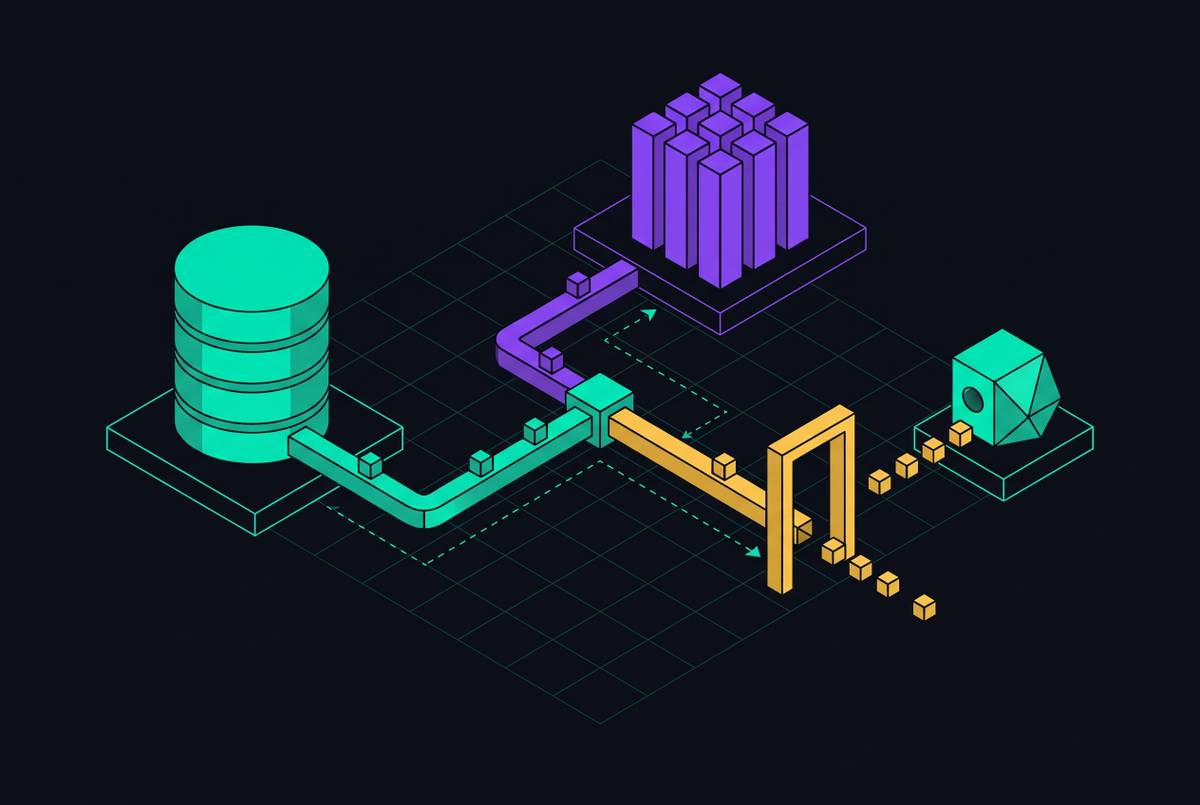
In a governed implementation, that request targets an exposed activation-rate metric rather than asking the agent to invent a calculation from tables. The server connects the request to the analytics layer, which supplies the defined result. The interface is now the governed data contract. A dashboard may consume the same contract, but it is no longer a required stop between a usage question and its answer.
Anthropic launched MCP as an open standard in November 2024, and it moved to neutral governance under the Linux Foundation. The MCP specification identifies 2026-07-28 as the current revision. Standardization replaces bespoke agent-to-data connections with a common interface on each side. An agent connected to a governed analytics layer can therefore ask the usage questions that layer exposes. The protocol supplies interoperability, and reliable answers require separately supplied business definitions and data-layer permissions.
Why MCP without a governed data layer produces wrong answers, not just unsafe ones
Column names and relationships do not, by themselves, define activation rate, churn rate, or monthly recurring revenue. The agent must infer those definitions before it can calculate anything. The database may run the SQL correctly but answer a different business question from the one the user meant to ask.
This is a definitional failure. With natural language-to-SQL over raw tables, the assembled formula depends on the model’s reading of names and relationships. That inference can differ between runs and models. Two agents can thus give different numbers for what seems to be the same question, even when neither has an access error. Read permission establishes that a query is allowed.
A semantic layer resolves that ambiguity by expressing metric definitions as machine-readable code. Formats vary, including YAML, LookML, and JavaScript, but the essential role is the same. The definition exists before the agent asks. Instead of assembling a formula from clues, the agent retrieves a metric contract, inspects its allowed dimensions, and submits a query bounded by that contract. The result returns with provenance.
For this reason, an analytics MCP server should expose semantic resources and query tools together. The agent needs to inspect what “activation rate” means before requesting its value. Otherwise, the definition arrives too late to constrain the calculation. This architecture also separates errors in interpretation from errors in access, because the business rule and the permission boundary are both explicit. Governance becomes part of answer correctness.
What pre-modeled metrics look like and why agents need them in that form
The useful unit for an analytics agent is a pre-calculated, named dataset with its definition, allowed dimensions, and provenance attached. It is not a free-form query. Pre-modeling means defining KPIs such as activation rate, churn rate, MRR, and weekly active accounts once in a centralized location. Those rules live outside reports and dashboards so that every downstream consumer can use them.
Each dataset needs a canonical name, a documented calculation, and a clear grain. The name gives the agent an unambiguous reference. The calculation keeps the business rule the same between calls, and the grain says whether the value is per user, per day, or per account. Without that last constraint, even a correctly calculated value can be aggregated at the wrong level.
Machine-readable definitions make these constraints available to software rather than leaving them in explanatory text intended only for people. The dbt documentation defines metrics in YAML, illustrating how a calculation can become a shared code artifact. What counts is that a dashboard, Slack alert, and AI agent receive the identical calculation through a governed API or query interface.
Pre-modeling limits what a query may mean. An agent can request a defined metric across its allowed dimensions without receiving authority to improvise a new business formula. This is the distinction between an agent-safe dataset and an on-demand calculation assembled from raw SQL.
How governance travels through the MCP connection when no human is in the loop
Without the UI, there is no last human check before an agent acts on data. Controls that the dashboard layer used to enforce must now be in the data path, including row-level filtering, access scoping, and metric versioning. The first step is read-only access. The plain Postgres MCP server runs queries in a READ ONLY transaction, preventing INSERT, UPDATE, and DELETE. A governed Parquet/DuckDB serving layer provides an alternative architecture in which the analytics connection has no write path to the application database.
Identity must constrain that read access as well. An agent using a shared service account inherits everything that account can see. With per-user or per-tenant authorization, the result is limited to what the requesting identity has permission to see. For an agency or fractional operator, those boundaries must separate clients at the governed layer. A conversational instruction is not a substitute for that boundary.
Every agent query should also have an audit trail recording its method, context, and timestamp. Missing traces obstruct debugging when an answer is wrong. These controls belong in the infrastructure through which requests pass, where a record of each request lets the team reconstruct why the agent produced an answer. MCP does not natively supply the organization’s access-control model.
The NSA’s Artificial Intelligence Security Center published “Model Context Protocol (MCP): Security Design Considerations for AI-Driven Automation” on May 20, 2026. The sheet states that MCP “lacks support for exchanging Role Based Access Control permissions at instantiation.” The July 2026 specification hardens authentication by requiring clients to validate a present iss parameter against the recorded issuer before redeeming an authorization code. It also requires issuer-keyed credentials and re-registration when the authorization server changes. Those requirements protect authentication, but they do not replace data-layer authorization or RBAC for the actions an agent infers it can take.
Supabase-specific risks that appear when an agent queries analytics data at scale
On Supabase, direct agent access to the application database combines semantic uncertainty with production risks. Connection exhaustion, write exposure, and schema opacity can emerge beyond local testing. Each has a different failure mechanism. Connection pressure concerns how requests reach Postgres, write exposure concerns the tools available to the agent, and schema opacity returns the problem of interpreting raw tables. A read-only connection addresses only one part of that combination.
Supavisor, Supabase’s cloud-native Postgres connection pooler built for multi-tenancy, mitigates connection pressure. The cleaner separation for agent analytics, however, is a governed serving layer that does not open a direct Postgres connection for each analytics request. Pooling and semantic governance solve different problems. A pooler can manage database connections, but it cannot supply the canonical definition of churn rate.
Tool exposure requires a separate decision. The Supabase MCP server includes Account, Database, Debugging, Development, Functions, Branching, Docs, and Storage feature groups, with tools that can write and alter schema. An analytics agent should not receive that surface. The plain Postgres server offers read-only transactions, but still exposes raw tables and leaves business definitions unresolved. Neither broad development access nor read-only table access is equivalent to a governed analytics API.
For production implementations, the recommended architecture stores MCP state in Postgres rows to enable zero-downtime scaling. It also instruments every request with method, context size, duration, and database latency, sending those records to a separate observability sink. Analytics queries then run through the governed layer rather than directly against the application database. The system can use Postgres for MCP state without making production tables the agent’s analytics interface.
What the agent needs to receive for usage analytics to be actionable without a UI
A raw MRR number is a value, while MRR with a prior-period trend and a target is a structured signal that supplies context the agent does not have to invent. A useful response contains the current value at the correct grain, with its canonical definition attached. It also contains change against the prior period and a benchmark or target derived from the governed definitions. These fields let the agent describe how the business is doing.
The same response structure applies to activation rate and churn rate. A current activation rate without a comparison says little about which way it is moving, and a trend without a benchmark leaves it unclear how much the change matters. The comparison must be defined too. A plan figure or historical comparison gives the agent an explicit reference, so interpretation does not depend on an assumed standard. Provenance ties that signal back to the metric the layer actually supplied.
For an early-stage startup on Supabase, the initial governed set should include MRR, churn rate, signups, activation rate, and burn rate. A sprawling KPI catalog is not an advantage if the agent cannot distinguish the definitions. Scope is part of usability for agents. A focused set makes it easier to choose the right metric and gives the people who use it the same shared vocabulary. “Revenue” should mean the same thing to a human analyst, a CEO dashboard, and an autonomous agent.
The agent can push signals into Slack, email, or a weekly digest. Headless analytics supports decisions where people already work by delivering signals with the same definition across destinations. The governed layer supplies the interpretation-ready result, and the agent delivers it without waiting for a dashboard visit.
How can early-stage teams adopt this infrastructure without a dedicated data engineer?
Early founders face a genuine bootstrapping problem. They cannot hire a data team before they have data worth analyzing, but analytics they can trust needs infrastructure. An agent makes missing definitions more costly because a plausible but incorrect answer can appear more useful than having no answer at all. The practical response is to adopt the semantic layer and observability infrastructure before hiring, much as a two-person team adopts Supabase.
For a team choosing a headless analytics backend, the relevant criteria follow from that constraint. The backend needs centrally defined metrics, governed API access, identity-scoped authorization, and query observability without requiring an opinionated frontend. Dashboard availability is not the deciding feature. Full API control is useful when it exposes reliable contracts, rather than transferring the work of defining every metric to the agent. A unified semantic layer also lets a calculation update propagate to the dashboard, Slack digest, and agent query alike.
Small teams can get analyst-grade answers this way without first hiring an analytics team. Agencies and fractional operators can use the same architecture for client reporting as long as the governed layer enforces the boundaries between clients. Skipping the UI is therefore not a shortcut around analytics infrastructure, but a deliberate choice about where its responsibilities live. The interface can disappear only when definitions, permissions, and traces remain in the data path.