Single Source of Truth Metrics for Multi-Stakeholder Startups
Governed, pre-calculated Postgres metrics give people and AI agents one number.
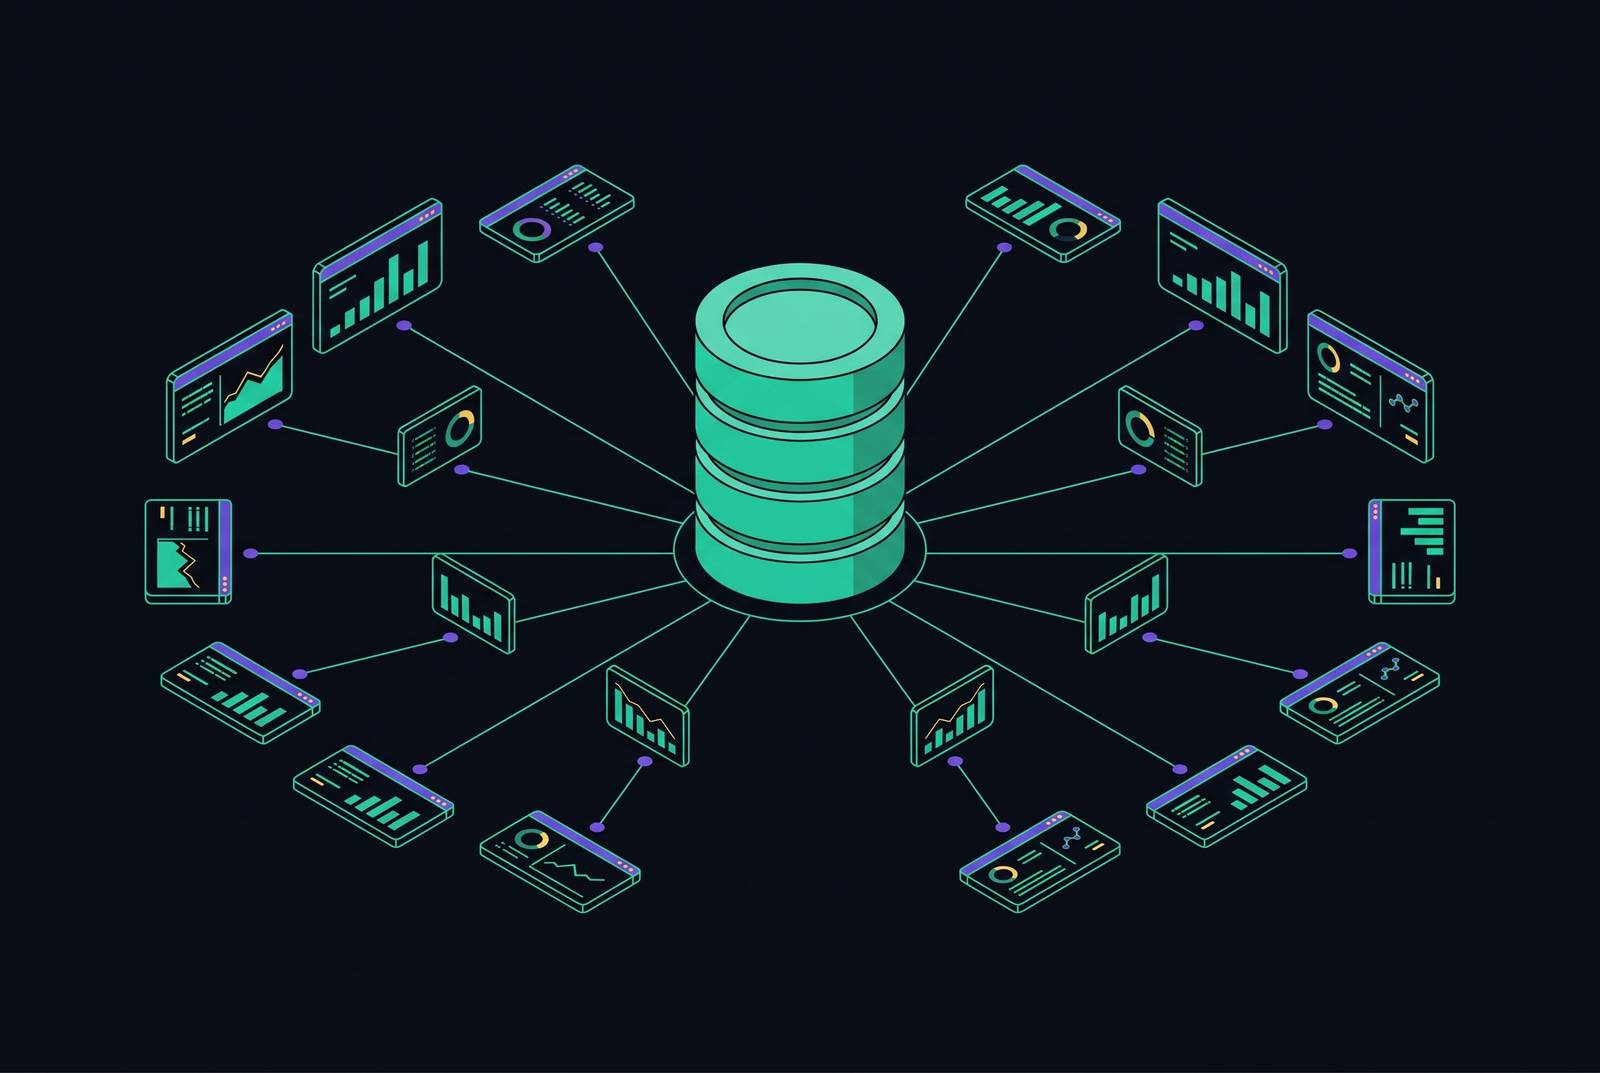
For Supabase SaaS teams that want API control without an opinionated frontend, the relevant analytics architecture is a headless, governed metric layer built around Postgres. A single source of truth requires agreed definitions, scheduled pre-calculation, and proactive delivery to every stakeholder. The same computed results can feed reports for people and AI agents without a prebuilt dashboard UI or a different reading of each metric.
Why startups with plenty of data still argue about the numbers
An all-hands reaches the financial update, and two slides show different MRR figures. Both figures have a defensible calculation behind them. Sales, finance, and product have each selected source tables, filters, or spreadsheets that fit their work. The teams disagree when those different readings have to become one answer for the whole company. Instead of deciding what to do, the executive team must first decide what the number means.
More data cannot settle what ARR or active users mean when each team does its own calculations. One engineer writes SUM(revenue), while another writes SUM(amount_captured), and their Q2 revenue figures diverge. Neither calculation necessarily looks suspicious in isolation. The difference can remain unnoticed until an audit forces the team to reconcile the results.
This is why metric drift is difficult to catch. No individual needs to make an obvious mistake for the company to lose a common account of its performance. An investor or board member asking for reconciled numbers exposes disagreements that routine reporting has allowed to persist. By then, trust in the data is already damaged. A strict data dictionary addresses the underlying ambiguity by giving terms such as “churn” and “active user” one agreed meaning.
What a single source of truth actually requires — and where most attempts stop short
A shared database is necessary, but it is insufficient. Two queries against the same table can produce different revenue figures because their filters and join logic differ. Agreement therefore has to precede query execution, rather than depend on whether individual analysts happen to make the same choices. The database establishes where records live. It does not, by itself, establish which calculation represents the business.
A data dictionary supplies that missing agreement by naming each metric, specifying its exact calculation, and identifying its authoritative source. ARR comes from billing, cash from the bank, and product usage from the analytics layer. A governed calculation layer then enforces those definitions so that a team cannot substitute its own SQL when requesting an official metric. These are distinct responsibilities within centralization. Most incomplete implementations stop at the dictionary, leaving enforcement to people while the document and queries gradually diverge.
The choice of metrics also requires discipline. Pre-PMF teams should focus on retention, activation, and qualitative pull rather than CAC payback or LTV, which need stable data that is not yet available. For most B2B SaaS startups at early traction, the core is CAC, LTV, monthly churn, ARR, and gross margin. Locking down an unsuitable set can be as damaging as having no agreed metrics. Even a minimal, stage-appropriate implementation improves on hand-synced spreadsheets, where every sync creates another opportunity to recalculate the answer differently.
How pre-calculated, modeled metrics close the governance gap that definitions alone cannot
To enforce the dictionary, the calculation must move into infrastructure. The appropriate unit of analytics is then a modeled, pre-calculated metric. The agreed formula runs against the canonical source on a schedule. Every consumer reads the resulting value. A dashboard, Slack report, investor update, and AI agent no longer need separate implementations of the same business definition.
This changes where interpretation is allowed to occur. Under independent on-demand querying, each request can introduce a different date range, filter, or join, even when everyone has read the same dictionary. Under governed pre-calculation, those choices belong to the metric model. The dictionary remains necessary, but it is no longer merely advisory. Its calculation is implemented before a stakeholder asks for the result.
The resulting dataset also resolves ambiguity for automated consumers. Starburst identifies the same underlying problem for humans and agents when metric definitions remain unresolved in the infrastructure. A human may ask which revenue column is authoritative, while an agent may select one and act confidently. Pre-modeled data removes that particular choice from the request.
A result is only as current as its last computation cycle, so a scheduled metric cannot promise the immediacy of every underlying transaction. For governing KPIs such as ARR, churn, and CAC, however, hourly or daily calculation is fresher than the weekly spreadsheet sync it replaces. Consistency is worth that trade-off for stakeholder alignment. Operational decisions that require real-time information have a different freshness requirement from the KPIs used to establish a shared view of the company.
Why pushing metrics to stakeholders outperforms waiting for them to pull
Consistent calculations do not guarantee consistent access to them. A sales lead who checks a dashboard regularly and a finance lead who last opened it earlier can arrive at the same meeting with different MRR figures. Neither needs to distrust the other for the discussion to stall. Stakeholders who do not check may continue using a stale mental model or their own spreadsheet.
A Monday morning Slack message can send the week’s ARR, churn, and CAC to every function lead simultaneously, using the same governed computation. The message gives the meeting a common starting point. Unlike separate dashboard visits, the delivery cadence establishes when the company receives its shared account of performance.
The same principle applies to a CEO dashboard that reconciles ARR from billing, cash from the bank, and usage from the analytics layer. Its value increases when that reconciled view arrives where stakeholders already work. An inbox or weekly digest can bring that view to them without changing how it is calculated. Delivery and definition remain separate responsibilities, but both are required for alignment. The same push infrastructure then becomes a mechanism for supplying AI agents with governed context.
What changes when AI agents become stakeholders consuming the same metrics
Agents turn an intermittent reporting disagreement into a continuous automated risk. An agent allowed to query production tables directly can construct its own interpretation of revenue, just as an unsupervised analyst can. Agents operate faster and at greater volume than human analysts. The agent also lacks the institutional memory that might help a person recognize an implausible interpretation. Metric governance therefore becomes more consequential without becoming a different discipline.
Direct production access adds an operational problem to the definitional one. lakeFS identifies agents as non-deterministic consumers that can traverse and modify data at speeds humans cannot monitor in real time. Direct analytical queries against production Postgres can exhaust the connection pool. Row-level security can also be bypassed when an agent connects as a superuser, a role with BYPASSRLS, or an unforced table owner. Even when the task is just to analyze data, raw database access lacks the safeguards of governed access.
The solution follows from the human reporting architecture. Agents can read the same pre-calculated datasets that supply stakeholder reports, rather than decide which tables and columns constitute an official metric. This constrains interpretation before the agent begins reasoning. It does not require confidence in the agent’s ability to reconstruct the dictionary correctly. The infrastructure has already resolved the metric definition.
Access scope complements that consistency guarantee. lakeFS identifies verifiable identities and least-privilege permissions as core requirements for agentic data management. An agent’s permissions should be limited to its specific task. That is the agent-facing expression of the same governance principle applied to human reporting. Each consumer receives only the data needed for its work through the governed layer.
How MCP turns a governed metric layer into a shared access contract for all consumers
The Model Context Protocol provides a standard interface to the governed layer. That interface allows agents, dashboards, and automated reports to use the same definitions without a bespoke integration for every consumer. The protocol’s standardization is limited to access. Its usefulness therefore depends on the operations and datasets exposed behind it. A shared interface only produces shared answers when it leads to shared calculations.
MCP’s three primitives contribute different parts of that contract. Tools can expose predefined, policy-enforced operations so an agent invokes a governed query. Resources can supply pre-calculated datasets and the schema context needed to interpret them. Prompts can provide reusable analytical templates that codify repeatable workflows.
MCP’s maintainers finalized a major specification revision on July 28, 2026, removing the Mcp-Session-Id header and protocol-level sessions. Anthropic technical staff member David Soria Parra described it as the most substantial change since the addition of authorization. Now that protocol sessions are gone, requests can go to any server instance behind a plain round-robin load balancer. Sticky routing is no longer required for those sessions. For a metric layer serving concurrent agents and human-facing tools, this simplifies horizontal scaling.
That transport change does not close the governance gap. MCP does not clean, transform, or govern the data exposed through it, so access to raw tables can still produce inconsistent numbers. The server must have the pre-modeled, pre-calculated layer behind it. Otherwise, the protocol only gives more consumers a standard route to the original ambiguity.
This separation defines the headless analytics pattern. Infrastructure is decoupled from any single frontend, while human dashboards, AI-generated reports, and autonomous agents read the same computed layer. For teams seeking API control without a prescribed interface, the relevant criteria are governed operations, scoped access, and reusable computed datasets. An agent can get product usage metrics through that interface without needing a prebuilt dashboard. The frontend becomes a consumer of analytics.
Building toward a governed metric layer on Supabase without adding infrastructure
For Supabase teams, the starting point is Postgres as the analytical home. The governed pattern can be implemented without an ETL pipeline or changes to the application schema by extending that foundation. It does not require a new warehouse stack. However, keeping Postgres as the home does not require every analytical request to go to the transactional primary. Workload isolation remains part of the design.
The practical starting set is ARR, cash, churn, CAC, and product usage, each with an authoritative input and an agreed formula. ARR comes from billing, cash from the bank connection, and churn from the subscription table. CAC draws on the ad-spend and signup tables, and product usage comes from the events table. Each metric produces one computed result. The team should first lock those definitions, calculate them on a schedule, and push them to stakeholders at the same time, before adding more ways to report them.
To protect transactional performance, analytical queries should run against a read replica or governed copy. Agents and tools that analyze data should use scoped credentials so row-level security can do its job. Pre-calculated results can then be stored as governed datasets and queried cheaply through DuckDB. This saves the live database from having to run expensive aggregations again for each request. Full API control need not mean unrestricted production access.
Observability helps keep that setup from becoming another dictionary that no one looks after. Teams with Supabase projects need to see which queries run, which metrics consumers ask for, and when calculations last finished. Those signals help teams catch drift before it becomes a stakeholder disagreement. The schedule and dictionary must remain live infrastructure. With that discipline, the ARR a founder reads in the Monday Slack digest is the ARR the AI agent uses to prepare the board memo.